



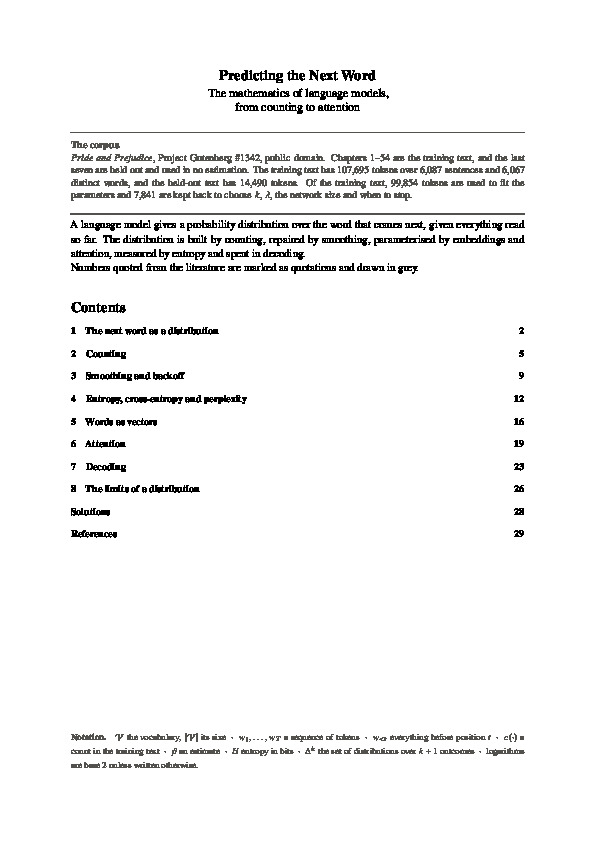
Next Words - Reading - The Mathematics of Language Models (pdf)
Next Words - Reading - The Mathematics of Language Models
-
- 0 Rating
- 0 Reviews
- 1 Students Enrolled
Next Words - Reading - The Mathematics of Language Models
Counting, smoothing, entropy, word vectors, attention and decoding on one novel
-
- 0 Rating
- 0 Reviews
- 1 Students Enrolled
- Free
- Course Includes
- PDF primer, 29 pages
- Quiz, 5 questions
Language Models N-grams entropy Attention Decoding
What you will learn
- Compute the probability and the bits of a sentence from bigram counts with the chain rule.
- Derive cross-entropy as the sum of entropy and KL divergence and read perplexity as an effective number of choices.
- Explain why attention scores are divided by the square root of the head width and how a next-word distribution changes w...
Courselet Content
1 components
|
|
587.7 K |
Requirements
- Probability, logarithms, basic calculus
General Overview
Description
After the words "he had", the training text of a novel contains 157 continuations over 86 different words, and the most probable of them has 15% of the mass. By the chain rule the probability of a sentence is a product of such distributions and its cost is a sum of bits. A bigram table filled by counting is 99.87% empty, and the zeros are repaired by add-k, Good-Turing and interpolation. The repairs are ranked by entropy, cross-entropy and perplexity in bits per character, from 2.520 for a uniform guess to 1.623 for an interpolated trigram. A network on word vectors has about 592 thousand parameters and a window of 3 words, and attention with a causal mask is a weighted average over every earlier position. Decoding is a separate decision, since greedy output has a cost of 3.04 bits a word against 6.98 for real prose.
Courses that include this CL
Recommended for you



Meet the instructors !
