



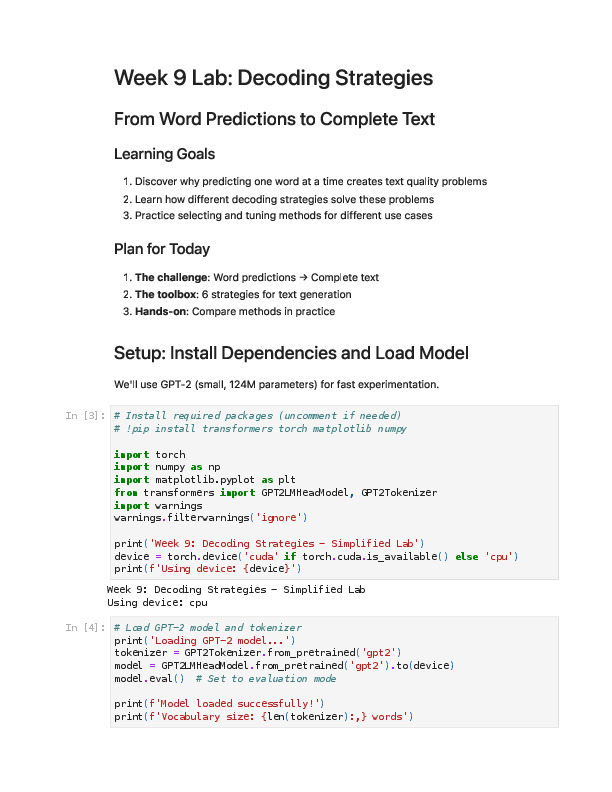
NLP Decoding Strategies (pdf)
NLP - Decoding Strategies Lab
-
- 0 Rating
- 0 Reviews
- 2 Students Enrolled
NLP - Decoding Strategies Lab
GPT-2 small experiments with greedy, beam, temperature, top-k and nucleus decoding and measures of diversity
-
- 0 Rating
- 0 Reviews
- 2 Students Enrolled
- Free
- Course Includes
- Lab notebook as PDF and .ipynb
- Quiz, 4 questions
GPT-2 NLP Decoding Text Generation Sampling
What you will learn
- Implement greedy decoding, beam search, temperature sampling, top-k sampling and nucleus sampling for GPT-2 small
- Measure diversity with distinct-n and count repeated n-grams in generated text
- Test how temperature, k and p change diversity and choose a method for a given task
Courselet Content
2 components
|
|
1.25 M |
Requirements
- Python with NumPy and PyTorch, probabilities and softmax
General Overview
Description
The next-token distribution of GPT-2 small, a model of 124 million parameters, has about 50,000 entries, and text is generated by choosing from it. Full search over all word combinations is impossible at this vocabulary size, and practical methods lie between it and greedy decoding. Students implement greedy decoding, beam search, temperature sampling, top-k sampling and nucleus sampling and compare the outputs for the same prompts. Diversity is measured as the ratio of unique to total n-grams (distinct-n), and repeated n-grams are counted. The change in diversity is measured over sweeps of temperature, k and p. In two exercises, repetitive greedy output is repaired and a method is chosen for each task. The 2025 deck on the same methods is courselet 1021, NLP - Decoding Strategies, From Probabilities to Text.
Courses that include this CL
Recommended for you



Meet the instructors !
